
RAG & evaluation / Sep 2026
CreditLens
Permission-aware lending RAG
Answers underwriting questions from borrower and policy documents with access controls, page-level citations, and continuous retrieval evaluation.
Architecture & evidence
Architecture
The problem
Lending questions need answers that respect document permissions and can be traced to the right source page.
System architecture
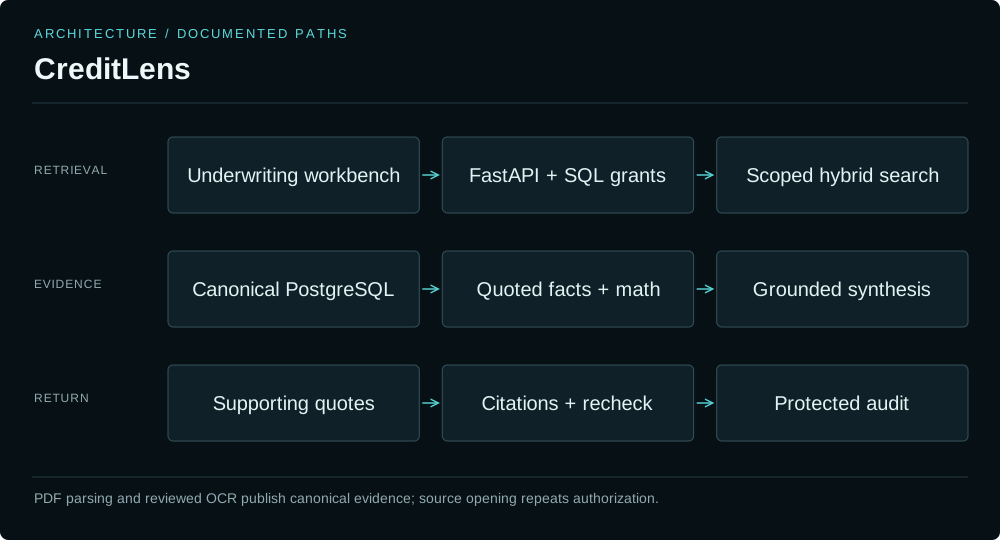
Hybrid retrieval, semantic chunking, selective query rewriting, and reranking feed a permission-aware answer pipeline with page-level citation enforcement.
Evaluation
A 240-question adversarial evaluation set covers policy interpretation, borrower evidence, missing documents, contradictions, restricted data, and underwriting exceptions.
Operating conditions
The 300 ms p95 latency result uses warm caching, eight concurrent clients, and two local API processes. Average cost per request was reduced by 31% to $0.043.
What I built
- Built a permission-aware lending RAG system across 3,800+ pages of synthetic policy and borrower documents using hybrid retrieval, semantic chunking, selective query rewriting, reranking, and page-level citation enforcement, achieving 86.54% Recall@10 and 0.788 nDCG@10, a 12.49 percentage-point improvement in retrieval recall.
- Created a 240-question adversarial evaluation set spanning policy interpretation, borrower evidence, missing documents, contradictions, restricted data, and underwriting exceptions, achieving a 92.5% grounded-answer pass rate while reducing unsupported claims to 1.7%.
- Implemented response caching, policy-aware access controls, end-to-end retrieval tracing, and CI quality, latency, and cost gates, improving answer quality by 13.4 percentage points, measuring 300 ms p95 latency at 8 concurrent clients across two local API processes with warm caching, and reducing average cost per request by 31% to $0.043.
Explore the implementation
Source code, setup instructions, and project documentation are available in the repository.